A Postgres pair whose primary is declared, not discovered
On Tue, 06 Oct 2026, by @lucasdicioccio, 3848 words, 12 code snippets, 3 links, 1images.
Generated from resources/postgres-pair.md — the repository is the canonical source, and may be ahead of this page.
A Postgres pair whose primary is declared, not discovered
Two machines, one Postgres cluster, and a sentence that says which machine is
the primary today. Changing that sentence moves the primary; nothing else
does. This is SreBox.PostgresPair, the salmon-pgpair binary, and
salmon-toy-qemu-pg-ha, a demo that builds its own machines to show it.
If you want the design argument rather than the instructions, read
specs/pg-switchover.md; this file is about
using what it describes.
What it is for, and what it is not
It is for a planned switchover (maintenance, a machine you want to drain) and an operator-decided failover, on two machines, where a few minutes of somebody’s attention is an acceptable price for the machine you did not buy. It is also, deliberately, a thing to break on purpose: every failure mode below is something the test suite causes and then asserts about.
It is not automatic failover. Deciding that a machine is dead needs consensus, consensus needs three voters, and salmon has neither — so this recipe never promotes on a hunch. When it cannot prove a promotion is safe it refuses, and the operator’s answer to a refusal is the one field that accepts a loss by name:
--may-discard A "I accept losing the writes on A that B does not have"
For the unattended-at-3am version, specs/pg-patroni.md
sketches the Patroni-backed shape, where salmon provisions and supervises and
Patroni decides.
The shape
Three kinds of node, and only one of them mentions a role:
| Node | Says |
|---|---|
member (one per machine) | how to be either half of the pair: replication settings, pg_hba lines for the peer (see "How the two members talk to each other"), the replication and rewind roles. Nothing about which half it is. |
bouncerSetup (one per bouncer) | pgbouncer's own configuration, and a routing file it includes but does not own |
pairRole | "this pair's primary is on B" — the only declaration an operator edits |
That split is the whole ergonomic claim: a switchover changes one node’s
declaration, so under run serve the machines underneath are not marked
stale by it, and an operator reading a diff sees one word.
pairRole’s check asks both machines and every bouncer what they are; its
up takes one step at a time until the declaration holds. The state is
re-derived every pass — observe, decide, act, observe again — so an up
killed half-way through a switchover is finished by the next one. There is no
progress file that could disagree with the machines.
Using it
salmon-pgpair config --primary A --a 10.0.0.2 --b 10.0.0.3 --bouncer 10.0.0.4 --seed B \
  | salmon-pgpair run up

salmon-pgpair config --primary B --a 10.0.0.2 --b 10.0.0.3 --bouncer 10.0.0.4 \
  | salmon-pgpair run up          # the switchover
run tree prints what the first of those declares before anything runs:
pg-pair-role (n2504805732311083189) primary of app is on A
  <- pg-pair-bouncer
  <- pg-pair-seed
  <- pg-pair-member
  <- pg-pair-member
pg-pair-bouncer (n671955809932212377) pgbouncer 10.0.0.4 in front of app
pg-pair-seed (7089073737010868211) seeds 10.0.0.3 from 10.0.0.2
  <- pg-pair-member
  <- pg-pair-member
pg-pair-member (n6118828710077022853) member of app on 10.0.0.3
pg-pair-member (2659614637461449593) member of app on 10.0.0.2
What it assumes was done before it ever ran, because a recipe that ships
secrets has chosen a transport for everyone who uses it: both machines have a
Postgres cluster and the two .pgpass files the pair names, and the bouncer
has pgbouncer, a userlist.txt and the .pgpass for its admin console. The recipe is given paths.
salmon-pgpair leaves all of that to you; a binary of your own can declare
it with the recipe below.
What it needs first
SreBox.PostgresPairPrereqs is that assumption written as nodes, for a
binary that composes the pair as a library. It still ships no secret: every
secret is a file already on the machine it is for, left there by whatever
your deployment uses to move secrets, and a SecretFile says where
(secret_from) and how it must be held (owner, group, mode). The recipe
installs it where the pair reads it. A file provisioned straight to its
destination (secret_from = Nothing) only has its owner and mode set.
| Node | Does |
|---|---|
memberPrereqs (one per machine) | installs the packages that are missing, checks a cluster of the declared name exists, and puts the replication and rewind passfiles where the pair names them, postgres:postgres 0600 |
bouncerPrereqs (one per bouncer) | the packages, the console passfile, and pgbouncer's auth file — copied only when it differs, and pgbouncer restarted (try-restart) only then |
applications (one per machine) | a pg_hba.conf line per application and client address, and, on whichever machine is the primary, the role, its password and the database it owns |
Prereqs.pairWithPrereqs reportPrint pair
    Prereqs.defaultPrereqs
        { Prereqs.prereq_repl_passfile = Prereqs.postgresOwned "/run/secrets/replication.pgpass"
        , Prereqs.prereq_rewind_passfile = Prereqs.postgresOwned "/run/secrets/rewind.pgpass"
        , Prereqs.prereq_console_passfile = Prereqs.postgresOwned "/run/secrets/console.pgpass"
        , Prereqs.prereq_userlist = (Prereqs.postgresOwned "/run/secrets/userlist.txt"){Prereqs.secret_mode = "0640"}
        , Prereqs.prereq_applications =
            [ Prereqs.Application
                { Prereqs.app_role = "app"
                , Prereqs.app_database = "app"
                , Prereqs.app_passfile = "/run/secrets/app.pgpass" -- on each member
                , Prereqs.app_clients = ["10.0.0.4"]               -- the bouncer, as the members see it
                , Prereqs.app_hba_method = "md5"
                }
            ]
        }
pairWithPrereqs is pairOp with those nodes in order: a machine’s
prerequisites before the pair’s own node for that machine, and the
applications after the role node. Things worth knowing:
- The auth file is the quiet one. pgbouncer reads
userlist.txtwhen it starts and not again, so a file written under a running process is a correct password that does not work. The restart happens when the file changed and only then, because any other restart drops the clients the bouncer is holding. The file is yours, in pgbouncer’sauth_fileformat, hashed however you chose; left in place rather than installed, nothing can tell it changed and restarting is yours too. - Applications come after the role node, not before the pair. A machine
about to be cloned is a pristine cluster that is not in recovery, and a
database created on it is exactly what makes
--seedrefuse to clone over it. So if a machine is unreachable the applications node for it fails, and says so, after the pair itself has converged. - A password is never in a script, an argument or a report. It is read on
the member (the fifth field of the passfile’s first line, as for the pair’s
own passfiles), fed to
psqlon standard input, and the one statement holding it has its output withheld: a failure there is reported in words. Rotating a passfile and re-running rotates the role. validatelists everything wrong with a declaration — names that are not plain identifiers, relative paths, an application claiming the pair’s own role — since these words end up in scripts run as root. A node whose declaration does not pass refuses to run.- An application’s
pg_hba.confline goes on both members, because that file is not replicated; the address is the client’s as the members see it, which need not be where the controller’s ssh goes. - With
--ssh-a/--ssh-b(member_ssh_host) nothing changes here: these nodes reach a machine exactly as the pair’s own do.
Getting those files there is a node the caller declares, not one the recipe
does: Salmon.Builtin.Nodes.SecretDelivery.uploadSecretFile puts a local
secret file on a machine over ssh with an owner and a mode, and
Gcp.SecretManager.secretFile has an instance read one out of Secret Manager
as itself. Either goes before the pair’s nodes; the recipe still only sees a
path.
--seed B is the first clone of a pair’s life. It is safe to leave declared —
the clone does nothing once the two sides share a system identifier, and
refuses a machine holding a cluster it does not recognise. It is not the way
back from a standby that has fallen too far behind (see the slot budget
below): that is --reseed.
Where to run it
On a machine that is not one of the pair’s two members: whatever runs
salmon-pgpair run up (or run serve, for a pair that is also watched) —
a CI runner, an admin box, a small third machine. Never on a member. Every
step reaches the members over ssh (a member that cannot be reached is
decided in seconds, not minutes), and the members are exactly the machines
that stop, restart, get partitioned and die: a controller on the old primary
is killed by the step that stops it, and one on a member that a partition
cuts off is cut off with it, from the very machine it needs to decide about.
Running it elsewhere is what makes “the member that dies” a case the
controller can observe rather than one it is inside of.
The controller does not have to be always up or unique-by-design: it keeps no
state (the section above), so a pass killed mid-switchover is finished by whichever
controller runs next (S2). What it does need is ssh to both members and to
every bouncer, as the users the declaration names, and salmon-pgpair itself
— the passwords stay on the machines in the .pgpass files the pair names,
never on the controller. In the qemu demo the controller is the process on
the host, outside all three guests, for the same reason.
The controller need not sit on the network the pair talks over. --a and
--b are the addresses the peer and the bouncers use — they go into
pg_hba.conf, primary_conninfo and the routing file — and by default they
are also where the controller’s ssh goes. When those differ, as on a cloud
network where an operator reaches a machine on its external address and its
peer reaches it on its internal one, say where ssh goes separately:
salmon-pgpair config --primary A --a 10.0.0.2 --ssh-a 203.0.113.1 \
                                 --b 10.0.0.3 --ssh-b 203.0.113.2 ...
(member_ssh_host in the directive, absent meaning member_host.) The ssh
address is the controller’s route and nothing else: no script sent to any
machine contains it, and reports, refs and the standby’s upstream comparison
all keep naming the member by --a/--b.
The controller need not log in as root either. Every script the pair sends —
the member and seed scripts, each step, the bouncer’s setup and probe, and the
prerequisite nodes — was written to be run by root: it appends to
pg_hba.conf, calls pg_ctlcluster, installs into /etc/pgbouncer, restarts
units. Stock cloud images refuse root logins, so name the login instead:
salmon-pgpair config --primary A --a 10.0.0.2 --b 10.0.0.3 --ssh-user ops ...
(member_ssh_user / bouncer_ssh_user in the directive, per machine;
--ssh-user sets all three, default root.) A login that is not root has
the whole script run under one sudo -n bash -c ..., so the scripts are the
same text whoever logs in and no line can be missed. That login needs
passwordless sudo: -n means a sudo that wants a password fails at once with
sudo’s own message, as a failed node, rather than waiting on a prompt nobody
will answer. root is sent what it always was, with no sudo in front, so a
machine with no sudo for root to go through is unaffected — though the scripts
themselves have always used sudo -u postgres, so sudo is installed either
way.
How the two members talk to each other
Streaming replication, the first clone, pg_rewind and the slot bookkeeping
are all connections one member makes to the other. What those connections must
be is a declaration (pair_conn_security), with three values:
--conn-security | pg_hba.conf on each member, for the peer | what the connecting side demands |
|---|---|---|
plain (default) | host ... md5 | nothing: libpq's sslmode=prefer |
tls-scram | hostssl ... scram-sha-256 | sslmode=require, or verify-ca/verify-full with --tls-ca |
tls-cert | hostssl ... cert | the same, plus a client certificate per role |
plain is the weak one and is the default on purpose: it is what every pair
was before the choice existed, and a recipe that tightened pg_hba.conf under
a running pair on upgrade would break replication on upgrade. It is fine on a
network nobody else is on, and not for replication that crosses anything
shared.
# encrypted, password proven by SCRAM, server not verified (Debian's self-signed cert is enough)
salmon-pgpair config --primary A --a 10.0.0.2 --b 10.0.0.3 --conn-security tls-scram

# and the server verified against a CA, each member serving its own certificate
salmon-pgpair config ... --conn-security tls-scram \
    --tls-ca /etc/postgresql/pair-ca.crt --tls-verify-full \
    --tls-server-cert /etc/postgresql/server.crt --tls-server-key /etc/postgresql/server.key

# and the two roles authenticated by certificate rather than by password
salmon-pgpair config ... --conn-security tls-cert --tls-ca ... --tls-server-cert ... --tls-server-key ...
Every file named is pre-provisioned on both members at the same path —
like the passfiles, the pair neither issues certificates nor moves them
(SreBox.PostgresTls can issue them; how they travel is yours). Keys are
postgres-owned and 0600. With tls-cert, salmon-pgpair expects the
client certificates at /etc/postgresql/salmon-{replication,rewind}.{crt,key},
each with CN equal to its role (replicator, rewinder); a binary using the
recipe as a library names its own paths (ClientCerts). --tls-verify-full
needs each server certificate to name the address given as --a/--b, so for
members declared by address, an IP subject alternative name. --tls-ca is also
what each cluster trusts client certificates against when --tls-server-cert
is given; without server files the cluster’s TLS settings are left as found.
What a pass does about it, and what it means for a pair that is already deployed:
- A pair that does not set the option is unchanged. Same two hba lines,
appended only if missing; no
sslmodein any connection; a directive written before the field existed parses asplain. The member script does gain two no-ops there: it looks for the stronger choices’ lines to remove (there are none), and compares a standby’sprimary_conninfowith what it would write (it is equal). - Changing the option replaces the pair’s own two lines per member; it does
not append beside them.
pg_hba.confis first-match andhostmatches TLS connections too, so an oldhost ... md5line left above a newhostsslline would keep accepting plaintext. Only the exact lines this recipe writes for this peer and these roles are removed; nothing else in the file is touched, and a wider line of your own above them still wins — the pair owns its lines, not the file. pg_hba.confis not touched until the cluster says it serves TLS. Ahostsslline on a cluster withssl = offmatches nothing, so the member node fails first, naming the reason, and replication carries on as it was.tls-certlikewise wants anssl_ca_file. Afterwards the server is asked (pg_hba_file_rules) whether it could load the file.- The running standby is brought along. Its
primary_conninfois rewritten (and reloaded) when it already points at its peer and differs from the declared one, so the stronger demand applies to the connection that exists rather than waiting for the next rejoin. The walreceiver reconnects once. Withtls-scramthe roles’ passwords are re-stored as SCRAM verifiers from the same passfiles. - The passfiles are still needed with
tls-cert: the roles are still given their passwords, though no line the pair writes accepts one.
This was exercised by hand on two Debian trixie containers (Postgres 17):
plain, then tls-scram on the running pair, a switchover, tls-cert with
--tls-verify-full, a switchover back, a fresh --seed, back to plain, and
both refusals. It has not been run in the qemu tier, nor on older Postgres.
What a switchover actually does
PauseBouncers -> StopMember A -> Promote B -> RepointBouncers B -> Rejoin A -> Done
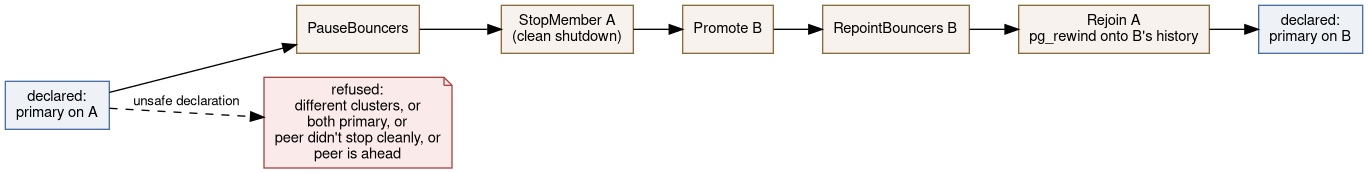
- PauseBouncers holds the clients rather than dropping them. With
pool_mode = transaction,PAUSEwaits for transactions in flight and queues what comes after, so a client sees latency where it would otherwise see an error. - StopMember is a clean stop, which hands the standby everything it has
not got, including the shutdown checkpoint the promotion waits for. It also
pins
wal_keep_sizefirst, because a clean shutdown ends in a checkpoint and a checkpoint recycles the WAL a later rewind reads. - Promote waits for the server to say it promoted.
- RepointBouncers rewrites the routing file,
RELOADs, andRESUMEs. Never a restart: a restart drops every client the bouncer is there to hold. - Rejoin brings the old primary back as a standby through
pg_rewind, onto the new primary’s history — same machine, same data, only the records that diverged replaced. Not a re-clone.
Traffic moves through pgbouncer’s admin console, and the routing lives in its
own file pulled in with %include. That is a seam between two writers:
bouncerSetup owns the ini, so a change there is applied by a restart; the
role node owns the routing file (bouncerSetup writes it only when it is
missing), and applies a change gently. One file with two writers is how a switchover becomes
an outage.
Several databases behind one bouncer
A pair often carries more than one database (an application and its side services), and one pgbouncer can route them all. Declare the others beside the first:
salmon-pgpair config --primary A --a 10.0.0.2 --b 10.0.0.3 --bouncer 10.0.0.4 \
  --db app --also-db jobs --also-db audit
In the directive that is bouncer_more_databases, a list of
{"routed_alias": ..., "routed_dbname": ...} beside bouncer_alias and
bouncer_dbname; a directive without the field is the one-database bouncer it
always was. Declaring a second Bouncer on the same machine is not the way:
both would write the same pgbouncer.ini and own the same service.
All of a bouncer’s databases live in the one routing file and move together:
each is PAUSEd and checked, the file is rewritten once with a line per
database, one RELOAD, then each is RESUMEd and checked. The role node asks
after every alias separately and requires all of them to agree — the old
primary is not stopped while any alias still passes writes, and the pair has
not arrived while any alias is held or pointed elsewhere.
- Adding a database to a bouncer that is already up needs nothing special.
bouncerSetupleaves the existing routing file alone, the role node finds the new alias going nowhere, and repoints: the file is rewritten with every database at the current primary and reloaded, without a restart. - Removing one from the declaration stops the pair from managing it; its line stays in the routing file until the next repoint rewrites the file.
- Refused: one alias routed twice on a bouncer, and an extra database name
that is not made of letters, digits,
_,-and.. - The databases, roles and
pg_hba.conflines themselves are the prerequisites’ (oneappentry per database), as is every user in the bouncer’suserlist.txt.
When it refuses, and why
A refusal is the recipe saying it cannot prove the next step is safe:
| It says | Because |
|---|---|
| the two machines hold different clusters | their system identifiers differ, so every step below would be applied to somebody else's data. Checked before anything else, and --may-discard does not override it |
| both machines are primaries | resolving a split brain means rewinding one onto the other, which is a loss. Name the side |
| the peer did not stop cleanly | a crashed cluster's pg_controldata records its last checkpoint, not the end of its WAL: the standby may be missing anything written after it |
| cannot confirm the peer has stopped | it is unreachable, and promoting without fencing is how two primaries happen |
| the peer standby is ahead | promoting the declared side would lose the difference |
And two verdicts that are not failures, and act on nothing:
AwaitStreaming— the peer is pointed here and not connected: a partition, or a standby that came back a second ago. Waiting is right; rewinding at it would stop it and then fail, because whatever keeps it from streaming keepspg_rewindfrom reading too.Degraded— the declaration holds but the pair is one machine short. Reported asUnknown, the one verdictrun serveacts on by continuing to look.
The slot budget
Each member streams with a replication slot the pair names, created by the
member that rejoins. A slot is a promise to keep WAL until the standby has it,
and an unbounded promise is how a machine that is merely down takes the
machine that is up with it — so max_slot_wal_keep_size caps it. Past the
cap the slot is invalidated, the WAL is recycled, and the standby can never
catch up.
That is a good trade and a terrible surprise, so the pair says it out loud:
the check reports the lost slot by name and does nothing. pg_rewind
would succeed and change nothing; the only way back is a re-seed, and wiping a
machine is an operator’s decision, declared with --reseed B (the side that is
not --primary). The declaration acts only on that one diagnosis — the
primary reporting that side’s slot lost — so it is safe to leave in place: a
healthy or merely lagging standby is never wiped. The pass stops the machine,
removes its data directory (only if it is this pair’s own cluster or empty;
a stranger’s is refused by name), clones it again from the primary, drops the
lost slot and lets the machine make its own. A pass killed half-way is
finished by the next one.
Watching it happen
salmon-toy-qemu-pg-ha builds three qemu guests, puts the pair on two of them
and pgbouncer on the third, and writes through the bouncer while the primary
moves:
t=$(cabal list-bin salmon-toy-qemu-pg-ha)

sudo $t config prereqs             | sudo $t run up   # once: three rootfses
$t config up --primary A --seed B  | $t run up        # once: the pair
$t config client --seconds 120     | $t run up &      # a client, writing
$t config up --primary B           | $t run up        # the demo
The client prints three numbers when it stops. On the machine this was written on:
  inserts acknowledged through the bouncer: 460
  inserts that came back an error:          0
  acknowledged rows missing afterwards:     0
The toy invents its own passwords — constants in its source — and is careful
to do only that with them: one node leaves files in /etc/salmon-toy-secrets
on each guest, playing the part of whoever provisions secrets, and everything
done with those files is SreBox.PostgresPairPrereqs, as in a deployment.
prereqs is the only part that needs root — debootstrapping a root
filesystem, regenerating an initrd that can mount a 9p root, and handing
/etc/ssh to whoever runs the rest. Everything after it is an unprivileged
user with two capabilities granted once (capsh needs cap_net_admin, qemu
needs cap_dac_override,cap_chown,cap_fowner; see
specs/qemu-test-vms-progress.md).
After the demo B is the primary: pause machine B’s guest, declare
up --primary A, and it refuses; add --may-discard B and the refusal turns
into a failover.
Driving it live
Each line above is a process that starts from nothing: it asks every node
again, does its one thing and exits, and to try the next thing somebody types
the next line. For working on a scenario — a person with a terminal, or a
program with a socket — the toy is better kept up. run serve --http boots
the guests once, holds them, and takes what is wanted of them a line at a
time, with every report on /events:
s=salmon-apps/scripts/qemu-pg-ha-serve.sh

$s serve &                 # the server: a unix socket in $XDG_RUNTIME_DIR, a web UI on 127.0.0.1:9081
$s guests                  # the bridge and three guests, answering ssh
$s pair A --seed B         # the pair on top of them
$s writer                  # a client the server holds, writing through the bouncer
$s tail &                  # its lines, live
$s pair B                  # move the primary
$s freeze b                # pause B's guest (qemu's monitor) ...
$s pair A                  # ... a failover is refused ...
$s pair A --may-discard B  # ... until somebody says what may be lost
$s thaw b                  # B carries on, finds it is no longer the primary, and is rewound
$s pair A                  # drop the licence again (see below)
$s down                    # clear everything, stop the guests, quit
Nothing in the script is more than a POST /command with one line of the
serve language (resources/serve-supervision.md §14); $s cmd '...' sends
any other, $s status/dag/events/tui read. An agent holding the socket
needs none of it: GET /help/seed is the vocabulary, GET /dag the state,
GET /events?since=N what happened, and POST /command?async returns at
once with the sequence number to read from.
Four seeds exist for this, beside up:
| seed | what it declares |
|---|---|
guests | the bridge and the three machines, without the pair. Every one of its nodes is one up declares too, so the two merge; what it adds is a second holder, so unpair takes the pair down and leaves three machines booted |
writer | the client as a process the server holds (managed). The one-shot client cannot be this: its up returns when its time is up and a pass waits for it, so the line that moves the primary would wait for the client it was meant to move it under. Its lines — a tally every five seconds, and one each time inserts start or stop failing — are the output stream and the node's ring in /dag |
frozen --machine M | a fault: M's CPUs are stopped. Its peers see a machine that went silent without closing anything. down resumes it |
partition --machine M --from N | a fault: M has a blackhole route for N's address, which cuts both directions. down removes it |
Things worth knowing before a session:
- Moving the primary is two lines, the new declaration and then
downof the old one, andpairdoes both. A seed is identified by the directive it configures to, soup --primary Bdoes not replaceup --primary A: for a moment both are live, the role node is reportedconflicting, the newer one wins and the pass that follows is the switchover. The two declarations name the same nodes and describe all but the role node identically (Test.QemuPgHaToySpecasserts it), so nothing is booted or provisioned again and retiring the old one takes nothing down.onlywould also move it, and would retire the guests, the writer and every fault with it. - A fault is a declaration, so it is state:
/dagshows which are in force, the loop re-applies one that went away by itself (a guest rebooted out of its blackhole route), andclearheals them before anything they stand on is stopped. - The server tends what it declared. Between commands every node with a
check is asked again — the role node included, over ssh to both members —
so a pair broken by a fault is noticed and, where the declaration allows,
repaired with nobody typing. That is the point, and also the reason to take
--may-discardoff again once a failover is done: left declared, it is a standing licence that the next pass will use.supervise offmakes passes the only thing that acts. - A paused guest is reported, repeatedly. Its “answers ssh” node fails
its check and its
upfails at once (it asks the monitor, rather than hold every later command behind two minutes of polling); the loop retries with backoff until the guest is resumed. - A guest killed outright needs no seed:
systemctl --user kill -s KILL salmon-vm-salmon-toy-ais a machine losing power, the unit isRestart=on-failure, and the nodes standing on it are tended as it boots.
What has been run: the declarations’ shapes (Layer 0), qemu’s pause, resume and run state against a real qemu process with no guest, and the server, the script and the held writer against a machine with no guests on it (the writer reporting that it cannot reach the bouncer). Not run: any of it with the guests booted — the session above, the blackhole route inside a guest, and the writer against a live pair are as written, not as observed.
What is tested, and what that is worth
Test.PostgresPairSpec covers the decision table at Layer 0 — every state two
machines can be found in, including every refusal — without a database.
Test.PostgresSwitchoverSpec and Test.PgPairDemoSpec cause the failures on
real machines:
| S1 | switch A→B→A with a client attached: every acknowledged insert present, zero client errors |
| S2 | the controller killed after each step in turn: a plain rerun finishes it |
| S3 | the primary crashed with un-replicated writes: refused without the flag, rewound with it |
| S4 | the two machines partitioned: the check is Unknown, and the standby is not touched |
| S5 | a failover across a partition that hides the primary from the controller too: two primaries, then the loser rewound |
| S6 | a standby that falls off the slot budget: said, not silently re-seeded |
| S7 | both machines stopped, in either order, and the stale one declared primary |
| S8 | a stranger's cluster where a member should be: refused, nothing deleted |
Between them these cost the recipe twelve defects, and not one was on the happy path: S1 and S8 found nothing, and every other defect needed a machine that stopped, or was cut off, without being asked to. That is the argument for writing the list as causes rather than as features.